graph TD
  A[Define Research Question] --> B[Specify the Data Generating Process]
  B --> C[Evaluate Data Quality]
  C --> D[Fit Model]
  D --> E[Check Model Assumptions]
  E -- Met --> F[Conduct Inference]
  E -- Unmet --> G[Check data or consider others models]
4 Model Preparation and Flow
This chapter provides a brief introduction to the steps involved in data analysis using linear mixed models and some thoughts on data quality and data interpretation.
Note
The steps explained below were applied to all examples in this tutorial.
Analyzing data using linear mixed models involves several key steps, from data preparation to model interpretation. Here’s a structured approach:
4.0.0.1 Example experiment
For the following steps, imagine we are running a field trial across 3 different locations. At each location, there is a cover cropping treatment with three levels and date of termination also with three levels. The experimental units are plots and are arranged across the three locations as thus:
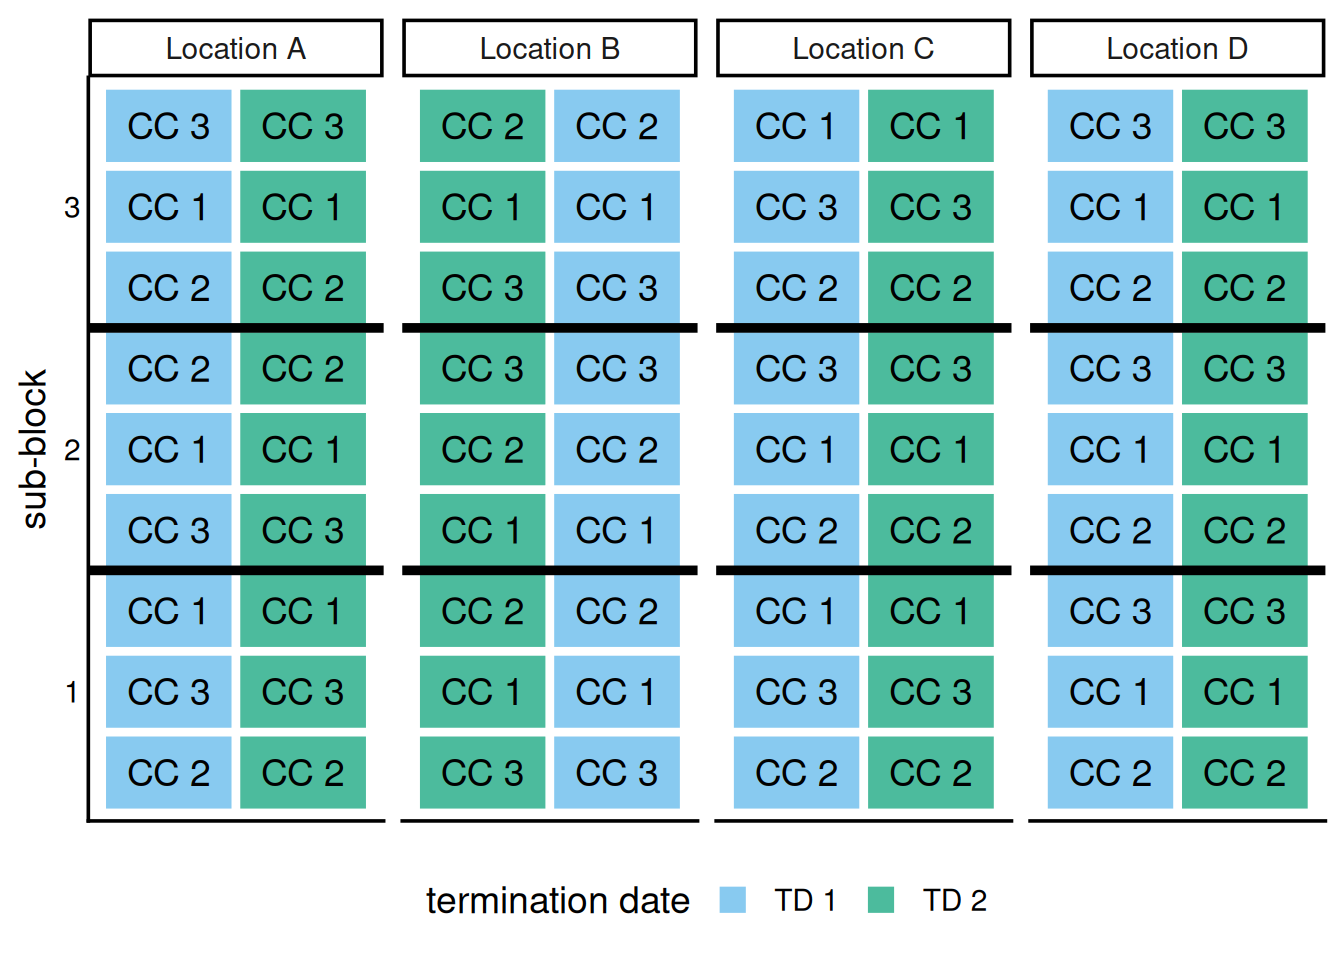
This is a complex design. At one level, it can be considered strip plot (also called “split block”) where the locations are blocks and there is one treatment, “termination date”. Nested within that are sub-blocks for the cover cropping treatment that is also applied in strips.
4.0.1 Step 1: Define the Research Question(s)
It is important to define what is your question that you want to answer with your research data because it directly influences the model specification, interpretation, and validity. Ideally, tgis was determined prior to design of the experiment and data acquisition. However, things change as an experiment unfolds, and sometimes experimental aims become lost in translation between the original grant proposal for a project and when the project is finally implemented. Before embarking on an analysis, write down the goals of analysis in the most precise terms possible. Examples:
How much does sugar beet yield change as the result of this new fertilizer source compared to another source?
What is the estimated change in milk yield with each unit increase in cow parity?
Does an experimental drug has a stronger effect on reducing cholesterol rates where a difference of 5 units or more is considered a meaningful result?
What are the relative contributions of location, year and cultivar influencing barley yield across southern Idaho?
The first two examples are asking for specific inference on the estimated effects of a particular intervention. The third example is a hypothesis test, and the fourth example is also inferential, but focused on variance instead of point estimates.
For the example study, the goal is to estimate the impact of termination date and cover cropping on several soil variables indicative of soil health. There is a particular interest in estimates for the interaction of termination date and cover cropping.
4.1 Step 2: Identity the data generating process
A linear model requires a linear predictor, that is, a statistical model specifying what will be estimated, the levels of replication and error terms estimated in the model-fitting process. Moving from a data set to the experimental design and model can be unexpectely challeging step, hence this section on design. The designs described in this guide are all “cookie cutter”, assuming you have already correctly defined the sources of variation and can plug your data straight into a model. However, we all can benefit from formally defining data-generated process. Misunderstanding the design can lead to errors in statistical analysis and conclusions drawn from the results (Bello and Renter 2018). So, let’s talk about how to properly identify and specify the data-generating processes from your study–that is, let’s discuss how to translate your study into a linear model.
Below are steps adapted from chapter 2 of Generalized Linear Mixed Models (Stroup 2013; Stroup et al. 2014).
The overall goal to outline what units received (or will receive) what treatment(s) and in what order?
Identify the treatments and their levels. Treatments are also called factors or interventions. They are independent variables whose impact on the dependent variable we want to estimate. Levels are specific categories or amounts of the factor applied to the experiment. A treatment could be nitrogen fertilizer, and the levels of that fertilizer could be two different types of fertilizer (e.g. urea and ammonium nitrate) or different amounts of fertilizer (20, 40, 60 lbs per acre). There may be multiple treatments or factors for a single experiment.
Identify the unit of replication (also called the unit of randomization). This is the smallest unit or entity that was independently assigned a treatment combination. This can be a spatial units of land (e.g. a plot), a person, an animal, part of an animal carcass, a single water sample, a soil composite for a specific depth, among many other things. This is not the same as smallest unit being measured; it is the smallest unit subject to a single combination of treatments. This is called the experimental unit.
Identify clusters or stratfication. This is the grouping of units of replication that we expect to be similar to each other in some way. In field experiments, this is often the block, but it may be an experimental run or it may also encompass other factors (e.g. locations, years). Survey statistical concepts of “clusters” and “strata” are akin. There are experimental designs without any clustering, but all the examples in this guide assume blocking.
Identify the unit of observation. This is often the experimental unit, but sometimes there are multiple observations within a single experimental unit, e.g. multiple measures of plant height at crop maturity, disease scoring for several potato tubers collected from a single plot, student in a classroom where the classroom is the unit of replication. In these cases, it’s important to ascertain how to express the dependent variables so that they reflect the unit of replication and are not artificially inflating the level of replication. A treatment combination was assigned randomly to an experimental unit and hence observations across experimental units are independent; two observations of the same unit at the same time are not independent. The unit of observation is always nested within the unit of replication.
Create a “plot plan” of the units that received what treatments and in what arrangement. Agricultural field plot maps are the general framework to use. While these represent relative physical locations of where each treatment was applied, the basic concept can be extended to other circumstances. Which animals in a dairy received a nutritional supplement, how were these animals grouped and how was the nutritional administered? If you are
Create an ANOVA table of the sources of variation impacting the dependent variables. We can use ANOVA as a tool for understanding how the experimental factors and clusters generate experimental data. List each source of variation and the degrees of freedom. Below is an example.
Note
Linear models also require that we identify the distributions of the dependent variable and the random effects, and identify a suitable link function for the dependent variable and its distribution. For this tutorial, all dependent variables and random effects are assumed to be normally distributed and use the identity link function (that is, specifying no transformation).
NoteExample
For the example experiment described above, the data generating process includes:
Treatments
- termination date (3 levels)
- cover cropping (3 levels)
Clustering Variables
- location (3 levels), randomization unit for termination date
- subblock (3 levels at each location), randomization unit for cover cropping
The experiment unit and observational unit are the same: a field plot.
ANOVA Shell for the Data-Generating Process
| Location | 4-1=3 | Location | 3 | ||
| Block | (3-1)*4=8 | Block | 8 | ||
| Termination Date | 2-1=1 | Termination Date | 1 | ||
| Cover Cropping | 3-1=2 | Cover Cropping | 2 | ||
| TD x CC¹ | (2-1)(3-1)=2 | TD x CC | 2 | ||
| TD Unit(location)² | (2-1)(4-1)=3 | TD Unit(location) | 3 | ||
| CC Unit(block)³ | (3*4-1)*(3-1)=22 | CC Unit(block) | 22 | ||
| CC Unit(block)|TD⁴ | (2*3-1)(4-1)(3-1)=30 | CC Unit(block)|TD | 30 | ||
| Total | (2*3*3*4) - 1 = 71 | Total | 71 |
\(^1\)“CC” refers to the cover cropping treatment.
\(^2\)Effect of termination date within location after accounting for location.
\(^3\)Cover Crop-within-block effects after accounting for cover crop effects.
\(^4\)Unit-within-block effects after accounting for all treatment effects.
4.1.1 Step 3: Conduct data integrity checks
The first thing is to make sure the data is what we expect. Here are the steps to verify our data:
4.1.1.1 Check the structure of the data
In this step, we need to make sure that the object class of each variable used in the analysis is correctly defined. For example, replication/block and year are often in the numeric format after import into R. But, for analysis the replication unit and other variables that are not truly numerical1 needs to be in a ‘character’ or ‘factor’ format. The dependent variable must also be in the correct format for its intended data type. For this tutorial, the dependent variable is expected to be numeric in all cases2, although categorical outcomes are certainly plausible for many studies.
1 The year “2026” is not correctly understood as 2,026.
2 Since this tutorial is exclusively focused on general linear models and is not addressing generalized scenarios at all.
Warning
Most R import functions (e.g. read.csv(), read_csv(), read_excel()) interpret continuously varying numbers (correctly) as numerical variables, but if they do not, that is often a signal that there is an unexpected character in a particular column of data that is incorrectly read as non-numerical. Perhaps a comma is present when a period is expected, or a cells reads as “N/A” instead of “NA”. This is an indicator to double check your data to ensure there are no errors or unexpected input in it.
We can use the command str() in R to look at the class of each variable in the data set.
str(dataset)This will print the data class of each variable present in the data set and a few example values for each variable.
The code below shows the conversion of rep from numeric to factor class and the conversion of yield from character to numeric class.
dataset$subblock <- as.factor(dataset$subblock)
dataset$location <- as.character(dataset$location)
dataset$y_var <- as.numeric(dataset$y_var)
Note that if your response variable did not import as numeric autommaticaly, this is an indicator that there may be problems with the observations that need attention.
TipFactor versus character class
Often, factor and character object classes are used interchangeably. However, we need to keep in mind the differences between these two classes. A character variable represents data stored in a text or “string” format. A factor variable is a categorical variable type with values stored as set levels. Most linear modeling packages in R expect categorical independent variables to be formatted as factors, but, many will automatically convert character variables to factors. Often, is is less complicated to use the character class for all factors used in analysis.
4.1.1.2 Inspect the independent variables
Running a cross-tabulation across treatments and replications is generally sufficient to make sure ensure the expected levels of these factors are present in the data.
table(dataset$cover_crop, dataset$subblock, dataset$location)
table(dataset$location, dataset$termindation_date)
The output from this code will give us the number of observations in each replication for a given treatment. It’s helpful to check (1) all the expected levels of categorical data are present and no additional levels are present (e.g., “high”, “High” or “High”); (2) the counts are as expected; and (3) what the balance of treatments is. Are they perfectly balanced? Slightly unbalanced? Very unbalanced? Is one treatment combination missing altogether? Depending on the context, these are resolvable issues.The main primary goal is to verify what the data looks like after import compared to your personal understanding of the data.
4.1.1.3 Check the extent of missing data
colSums(is.na(dataset))This will give you the number of missing values in each variable. Missing data are a normal part of experiments and in most cases, are not a problem. However, if there is more missingness than expected, it is good to check that the data are correctly entered and that nothing went wrong during data import.
TipMissingness versus zeros
We occasionally see users substitute missing data with zeros. This is not recommended unless there is a clear justification for this choice. If in the course of an agronomic trial, one plot (that had been seeded for some crop) failed to produce any crop at all due to a field conditions (e.g. drought, disease), it is reasonable to assign a zero to that plot for a variable we expected to measure such as total biomass. However, if due to some error or choice, a plot was not seeded with a crop and hence produced no crop during the field seasoln, assigning a zero is not an accurate description of what occurred (again, assuming we are measuring a crop variable such as biomass). Likewise, it not appropriate to treat true zeros as missing. Sometimes highly unusual conditions can occur, for example, a deer eats the entirety of a field plot. In these unusual instances, it is up to the researcher to decide if these conditions reflect a common reality they want incorporated into the final estimates (assign the plot as “zero” or the closest appropriate value), or exclude that observation (i.e. set the data for that plot as missing).
4.1.1.4 Inspect the dependent variable and all other continuous variables
Check the dependent variable and all continuous variables (i.e. covariates) to ensure their distributions are following expectations. A histogram is often sufficient to accomplish this. The goal of this step is to verify the distribution of the variable and to make sure there are no anomalies in the data such as zero-inflation, right or left skewness, or any extreme observations (high or low). This is designed to be a quick check, so there is no need to spend time prettifying these plots.
hist(data$soil_organic_matter)Data are not expected to be normally distributed at this point, so don’t bother running any normality tests like the Shapiro-Wilk test. This histogram is a check to ensure that the data are entered correctly and are within a valid range of values. Evaluating this requires a mixture of domain knowledge and statistical training. Over time, as you look at these plots regularly, you will develop a sense of what your data should look like at this stage.
4.1.1.5 Next Steps
The purpose of these checks is to help find any data errors that ought to be fixed prior to model fitting. These checks are designed to be done quickly and should be conducted for every analysis if you have not previously inspected your data as thus. We do this before every analysis and often discover surprising things! It is best to discover these things early, since they are likely to impact the final analysis.
If do you identify issues, check your data and correct as necessary. Once a data set passes these checks, we can move to next step: model fitting.
4.1.2 Step 4: Fit the Model
4.1.2.1 Notes on formula syntax and expectations
In this guide, we use ‘lme4’ and ‘nlme’ packages to fit linear mixed models. These packages have overlapping functionality and follow a similar framework and syntax. The general framework for lmer() and lme() models is to specify the response variable, fixed factors, and random factors and follow the R generic function for formula(). For this demonstration, let’s assume the dependent variable is ‘yield’, ‘tr’t is a fixed effect and ’block’ is a random effect.
4.1.2.2 Example
The code below shows the R syntax for a mixed model using the package ‘lme4’. It is possible to run this model in ‘nlme’, but the degrees of freedom must be calculated manually.
model_lmer  <- lmer(yvar ~ cover_crop*termination + (1|location/termination) + (1|block/cover_crop),
data = dataset)dataset$one <- factor(1)
model_lme <- lme(yvar ~ cover_crop*termination,
random = list(one = pdBlocked(list(
pdIdent(~ 0 + block),
pdIdent(~ 0 + block:cover_crop),
pdIdent(~ 0 + location),
pdIdent(~ 0 + location:termination)))),
data = dataset)The parentheses are used to indicate a random effect, and this particular notation (1|block) indicates that a ‘random intercept’ model is being fit 3. This is the most common approach. It means there is one fit for each block. Here, note that random effects are specified differently in the lmer() and nlme() models.
3 Please refer to Chapter 3
Tip
na.action = na.exclude
You may have noticed the final argument for na.action in the model statement.
The argument na.action = na.exclude provides instructions for how to handle missing data. The option na.exclude removes the missing data points before proceeding with the analysis. When any observation-level model outputs is generated (e.g. predictions, residuals), they are padded in the appropriate place to account for missing data so they can be easily merged into the main data set if need be.
Even when there are no missing data and this step is not necessary, it is a good habit to be in.
4.1.3 Step 5: Check model assumptions
Linear mixed models rely on independence of the observations, normality and homoscedasticity of residuals and linearity between the dependent and independent variables. Violating these assumptions can lead to biased estimates, incorrect inference, and model convergence issues. Always check model assumptions, and if they are unmet, consider alternative model specifications.
Note‘iid’ assumption for residuals
In these model, the error terms, \(\epsilon\) are assumed to be “iid”, that is, independently and identically distributed. This means they are expected to be normally distributed with a mean of 0 standard deviation of \(\sigma\), or more specifically, \(\sigma \mathbf{I}\), which refers to constant variance and a covariance of zero between residuals.
In this guide, we well be testing these assumptions by using graphical methods. This can be done in two ways:
4.1.3.1 Original method
We can use base plot() function in R for ‘lme4’ and ‘nlme’ modelling objects to check the homoscedasticity (residuals vs. fitted values plot) of residuals.
plot(model_lmer, resid(., scaled=TRUE) ~ fitted(.),
xlab = "fitted values", ylab = "studentized residuals")plot(model_lme, resid(., scaled=TRUE) ~ fitted(.),
xlab = "fitted values", ylab = "studentized residuals")In this output, we expect to see a plot with random and uniform distribution of points. If we notice any specific pattern in the distribution of points, we need to look into the model structure and response variable distribution closely.
To check the normality of the residuals, we need to extract the residuals first using the resid() function and then generating a qq-plot:
qqnorm(resid(model_lmer), main = NULL); qqline(resid(model_lmer))qqnorm(resid(model_lme), main = NULL); qqline(resid(model_lme))Interpretiong qq-plots: if residuals falls closely along the 45-degree qq-line, it suggests normality of the residuals. It is common see mild deviations at the ends of the distribution, and since these models are robust to modest deviations from normality, that may not be a concern. However, if there is strong deviation of residual points from the qq-line, consider a different model that fits the data better. How to do this is beyond the scope of this guide, sorry!
4.1.3.2 New Method
Nowadays, we can take advantage of the performance package, which provides a comprehensive suite of diagnostic plots.
The diagnostic plots we created above can be created using one function check_model() from the ‘performance’ package.
Note
Read the documentation for check_model() to find what other checks this function can do. If you would like to check all assumptions at once you can use the argument check = "all".
check_model(model_lmer, check = c('normality', 'linearity'))check_model(model_lme, check = c('normality', 'linearity'))4.1.4 Step 6: Conduct inference
After verifying the assumptions of model, we can move to the inference of model. Based on analysis goals, we can either conduct analysis of variance using anova() function and/or we can estimate marginal means using emmeans() function from the ‘emmeans’ package. We can also run post hoc comparisons to evaluate the pairwise comparison or contrasts using estimated means.
WarningModel assumptions & statistical inference
Please remember that conclusions should not be drawn from models that do not meet linear mixed model assumptions.